Get $150 in Free GPU Credits
Purchase the book and receive $150 in free GPU credits on Lambda. Simply email your proof of purchase to author@thedrlbook.com to claim your credits.
Deep reinforcement learning (deep RL) has transformed what machines can do. Self-driving cars carry passengers on public roads, robots learn to walk and recover from a stumble instead of replaying pre-programmed motions, and language models write working code and prove theorems long considered hard. None of this behavior was written by a programmer: the machine learned it all from experience. These methods are moving out of research labs into ordinary engineering work, making an understanding of their mathematical foundations and inner workings crucial for engineers who want to stay competitive as more systems are built this way.
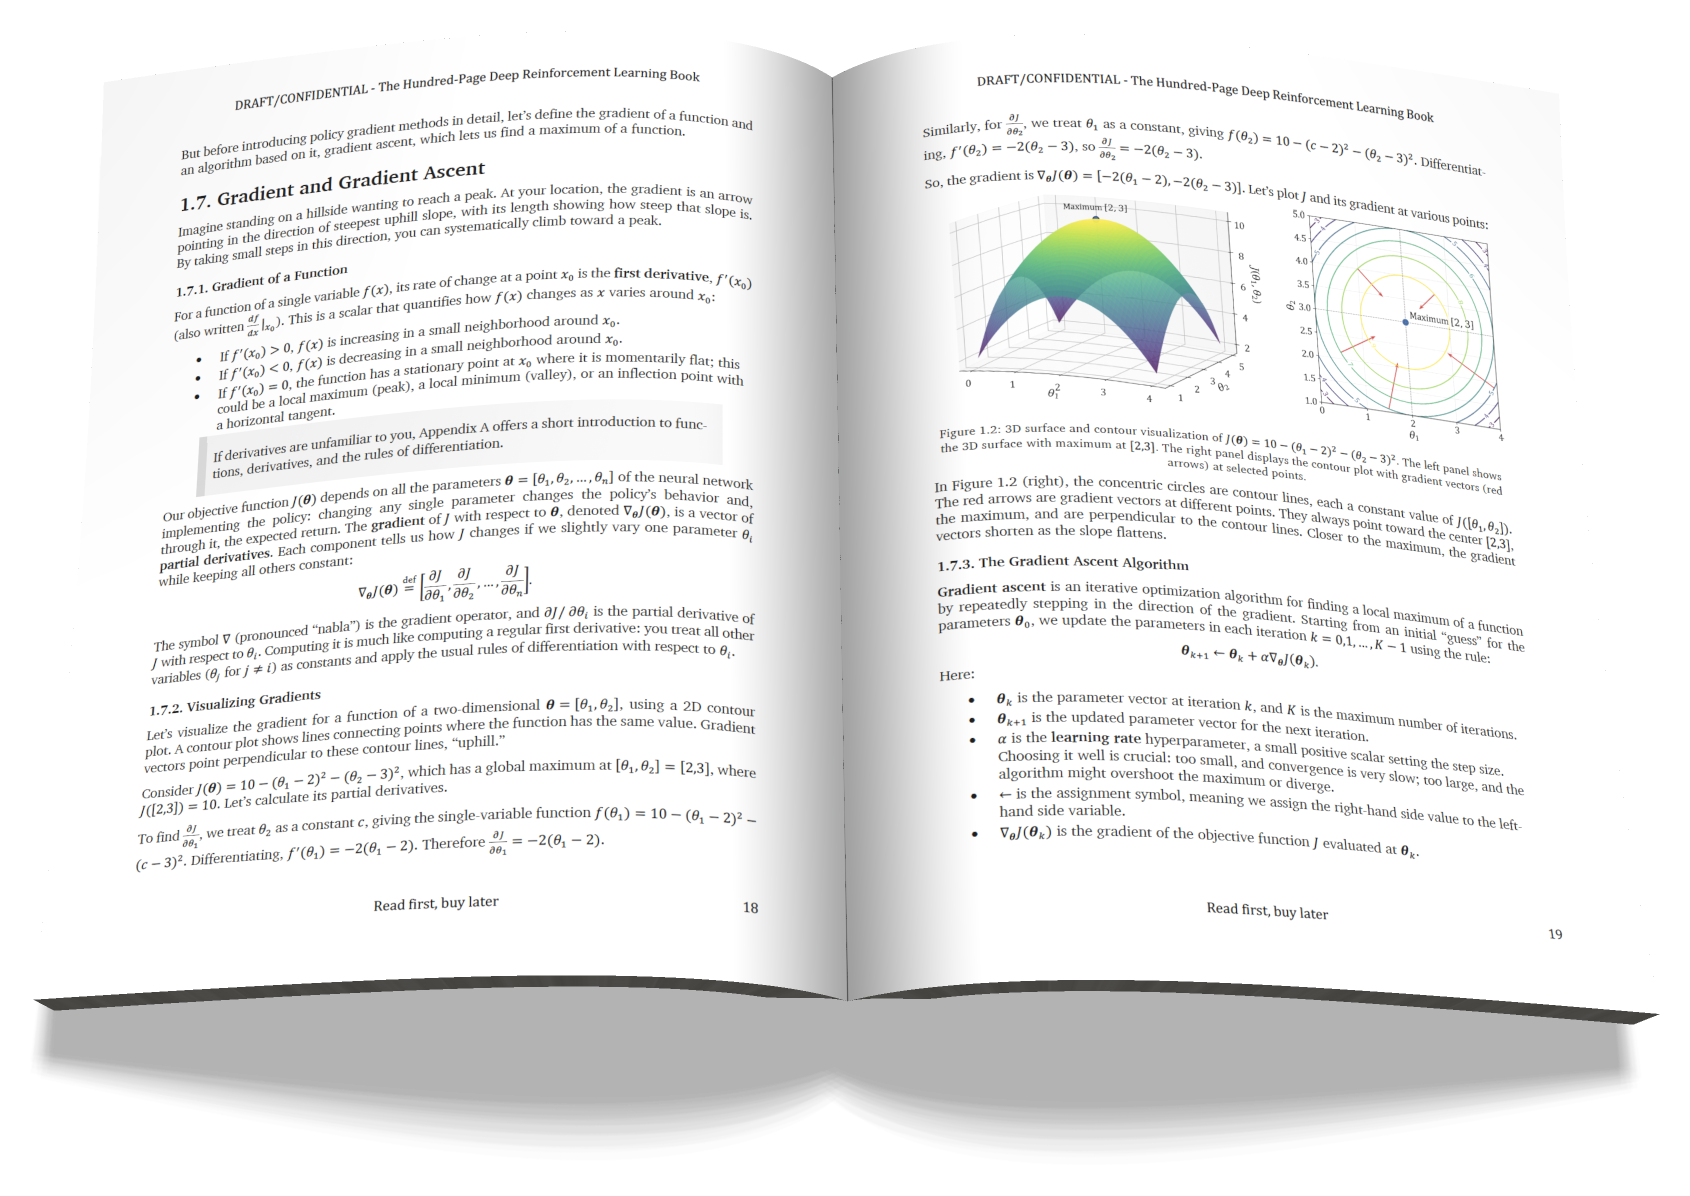
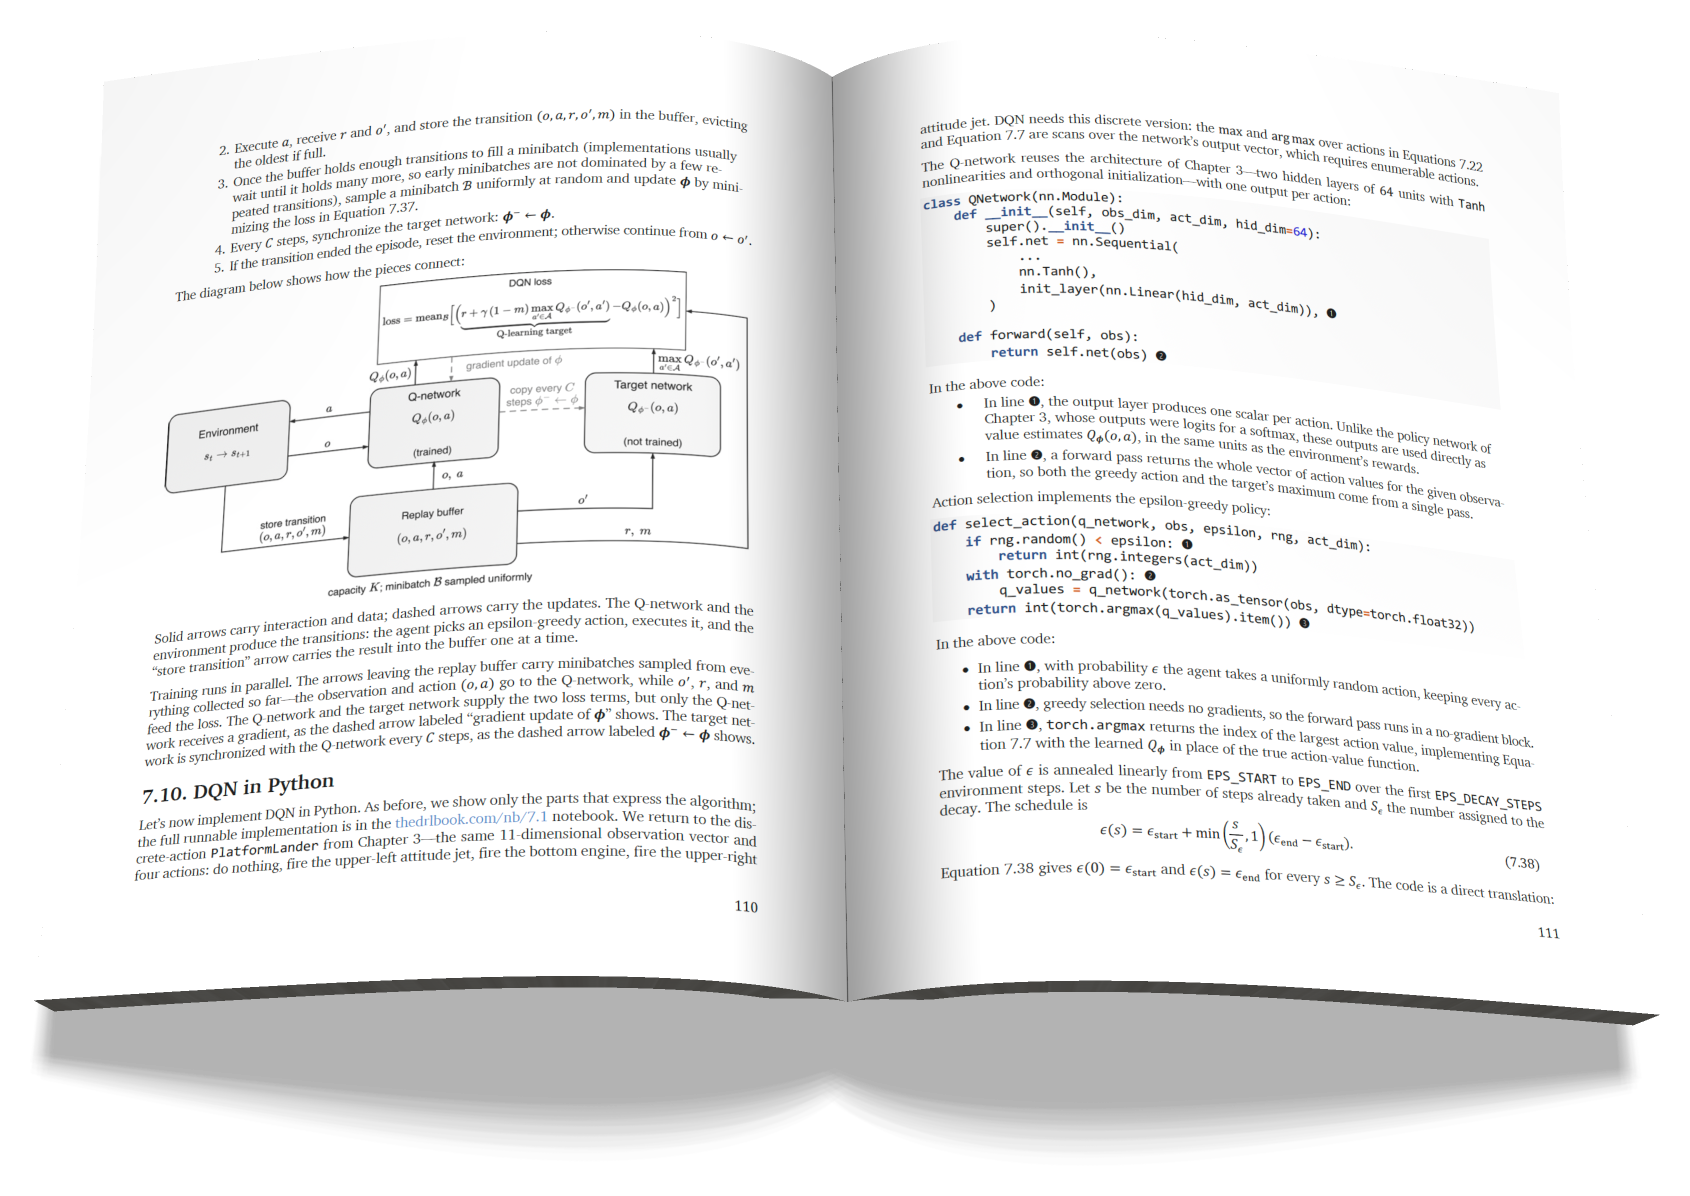
This book traces the evolution of deep RL algorithms. It starts with on-policy learning and the Policy Gradient Theorem that gave rise to a family of actor-critic methods, including Proximal Policy Optimization (PPO) used to train both walking robots and large language models. Each algorithm builds on previous results, so every choice is justified. The book then turns to off-policy algorithms and derives the Deep Q-Network (DQN) from first principles. Every concept is motivated, grounded in clear mathematical foundations, and illustrated with graphs and working Python code.
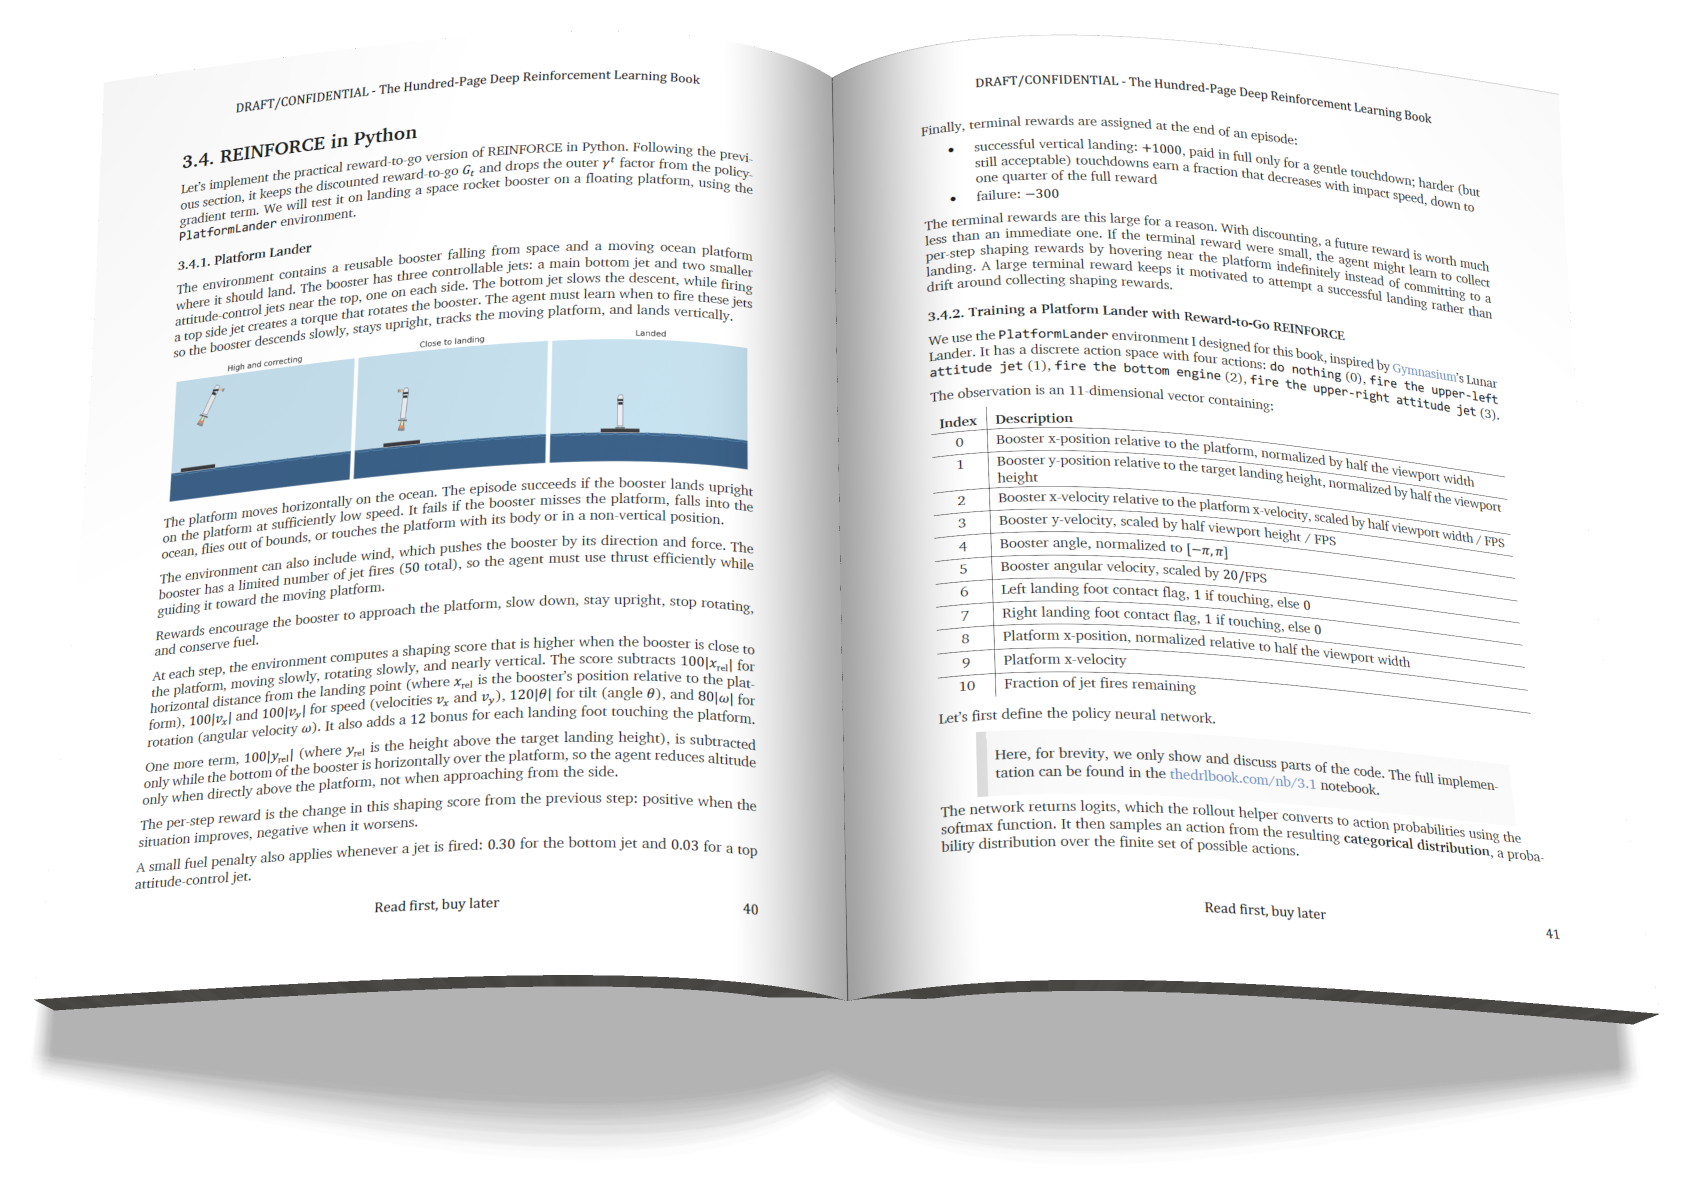
Everything in the book is meant to be run. Each algorithm is implemented from scratch in PyTorch and trained on the same task—landing a reusable rocket booster on a moving ocean platform—so you can compare the algorithms side by side and see what each new idea changes. The closing chapter applies these methods to large language models: how a generated response becomes a trajectory, how RLHF trains reasoning models without a learned critic.
What's inside?
Is the book for you?
Whether you're a technical leader, engineering manager, software developer, data scientist, or machine learning engineer, this book provides both the theoretical depth and the practical implementation skills essential for working with reinforcement learning—from robotics and control to finetuning language models.
Purchase the book and receive $150 in free GPU credits on Lambda. Simply email your proof of purchase to author@thedrlbook.com to claim your credits.
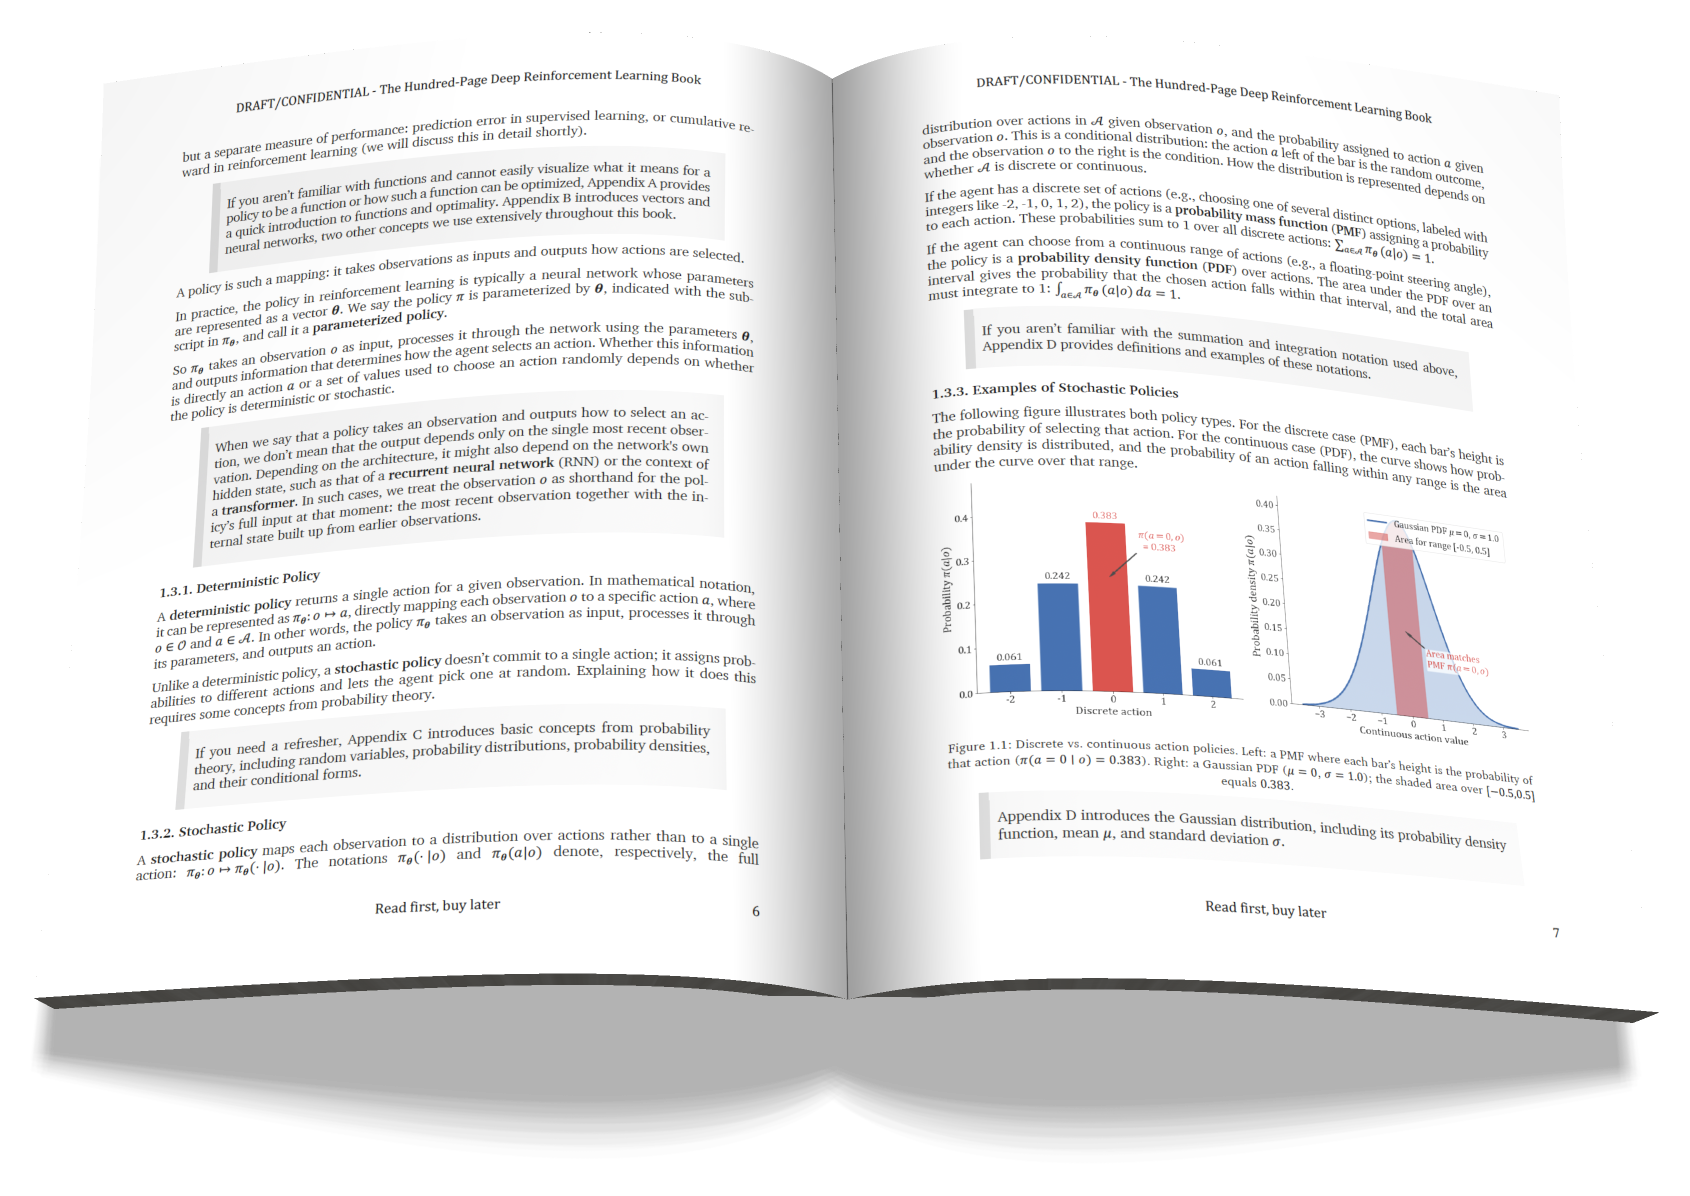
This book is published on the read-first, buy-later principle. All chapters will always remain available on this website.
Andriy Burkov is the author of "The Hundred-Page Machine Learning Book" and "The Hundred-Page Language Models Book," both of which became #1 Best Sellers on Amazon. He holds a Ph.D. in Artificial Intelligence and is a recognized expert in machine learning and natural language processing.
As a machine learning expert and leader, Andriy has successfully led dozens of production-grade AI projects in different business domains at Fujitsu, Gartner, and TalentNeuron. His books have been translated into more than a dozen languages and are used as textbooks in many universities worldwide. His work has impacted millions of machine learning practitioners and researchers worldwide.
Andriy's app: ChapterPal - an AI reading tutor for learners.
Stay in touch: LinkedIn, X, email, newsletter
Support Andriy by becoming a patron on: Patreon, Substack, or Buy him a Coffee